


Search here
Can't find what you are looking for?
Feel free to get in touch with us for more information about our products and services.
 Use Cases
Before It Trends: Social Listening at Scale for a Global FMCG Brand
Most brands don’t know what to monitor when they come to you. There’s no keyword list waiting to be handed over, no tidy set of hashtags someone already tracks. That decision hasn’t been made yet, and it turns out to be most of the work.
Meanwhile, the thing worth tracking is already moving. New words and new trends show up in a reel or TikTok before they show up anywhere else. All before Google Trends catches them, before they move a sales number.
By the time a trend is measurable through the normal channels, it’s already peaked. By the time a trend is visible enough to act on, it has already peaked. Development takes months, and you launch into a crowded market just as attention moves on.
Trend-chasing is a lagging strategy. Winners spot the underlying need early, before it becomes a trend, and build for that.
This is what social listening at scale actually means.
Social listening is the practice of monitoring social media for what people are saying about a brand, category, or topic. It involves tracking mentions, keywords, and trends as they show up in real posts, not in a survey or a focus group.
Most people assume the hard part is the listening itself: pulling posts off Instagram, TikTok, Reddit, or X at scale. It isn’t.
The real work is deciding what actually counts as a trend, and proving it before it’s obvious to everyone else.
That’s exactly the problem Grepsr solved for a global FMCG brand’s chocolate business.
About the Client and Their Requirements
Our client is a global FMCG brand, trying to understand what was actually moving inside their chocolate category on social. All before it showed up anywhere else that mattered like a sales number, a competitor’s launch, a shelf.
The result from our end had to be something they could actually act on, not just an interesting chart.
That set the requirements:
- Build the keyword and trend taxonomy from scratch, for chocolate specifically, not adapted from somewhere else.
- Go beyond captions and hashtags, capture the language in the video itself, where new vocabulary shows up first.
- Separate a real trend from noise: a single account’s flood, a piece of brand-driven content dressed up as demand, a spike that’s really just sponsorship.
- Screen every finding against real commercial constraints, so what gets delivered is launchable, not just noteworthy.
- Prove the approach on one category before scaling it anywhere else.
To validate before committing further, Grepsr ran this as a proof of concept on chocolate: a fixed panel of a thousand UAE-based influencer and general user accounts. Tracking their content continuously, alongside a broader keyword search layer to see what the category currently looked like.
The Challenges
1. There was no keyword list to start from, and no obvious one to write.
Most listening projects start with a taxonomy already in hand. This one didn’t. Nobody had defined what counted as a relevant trend for chocolate in this market, and a lot of the real conversation wasn’t even happening in a language an English-only brief would think to check.
2. Real demand and a templated flood look identical by volume alone.
A single bakery posting the same caption thousands of times can outrank a genuine, slow-building trend, if all you’re counting is how many times a term shows up. Raw volume doesn’t know the difference between a thousand people talking and one account on a schedule.
3. A brand’s own marketing can pose as consumer demand.
A sponsored post or a piece of branded content can post a huge spike on a term that has nothing to do with what people actually want. Counted the wrong way, that spike looks exactly like a real trend forming.
4. A keyword scrape alone always looks like it’s trending up.
Anything pulled from a general keyword search is recency-biased by construction. As recent posts are just easier to retrieve. A trend line built only from that kind of data slopes upward whether the trend is real or not.
Grepsr’s Approach
1. Two corpora, two different jobs.
We built and tracked a fixed panel: the same set of UAE-based influencer and general user accounts, followed continuously over time. That’s the only place we ever drew a trend line from, because it’s the only data that isn’t biased by what’s easiest to pull.
Alongside it, we ran a broader keyword search layer, used to understand what the category currently looked like and to discover new entrants.
2. Six ways of finding a keyword, because no single one catches everything.
We run several complementary approaches over the same raw content, and each finds what the others miss:
- Cultural vocabulary: the words people actually use, which no English-language brief would predict. We also stress-test what we find. One high-signal term turned out to be paid promotion, not real demand, so it was filtered out.
- Local phrasing: expressions tied to specific occasions and buying moments.
- Context words: terms used constantly in conversation but rarely tagged, like the language around weddings, graduations, and celebrations.
- Brands and products: including ones with thin evidence, which we keep and flag rather than discard.
- Adjacent discovery: following connections outward from known terms to surface players nobody had listed, including emerging brands.
- Pain points: complaints buried in the text, which show a term matters to someone, not just that it’s popular.
3. Screening the noise out before it reaches anyone.
- A single account posting the same templated caption thousands of times gets excluded as a flood, because a real trend has many different people talking, not one account with a scheduler.
- Ambiguous terms: a word that means two completely different things depending on context gets qualified with context rules instead of thrown out, so we don’t lose real signal just because a term is hard to parse.
- Anything that looks brand-driven or partner-driven is kept, but flagged, so nobody mistakes paid visibility for organic demand.
4. Ranking and publishing.
Surviving candidates get scored on how strong and specific their evidence is, then capped, so the list never balloons into thousands of loosely-related terms. What makes the final cut gets tagged with exactly how it was found, so no keyword’s relevance has to be taken on faith, and given a priority tier that decides how often it gets rechecked.
None of that is permanent. The whole list gets re-versioned on a fixed schedule. So a term that keeps growing across more than one platform for a full quarter gets promoted automatically.
5. Two rules decide what’s actually a trend.
A term only gets flagged as an emerging trend when it clears one of two bars:
- Engagement-outlier rule – a single post using new or unusual vocabulary pulls in engagement wildly above the category norm.
- Momentum rule – a term’s volume keeps growing month over month, for more than one consecutive month, off a real base, not a handful of posts.
Both rules run monthly against the fixed panel, because that’s the only data clean enough to trust the comparison.
6. A fixed set of questions, asked the same way every time.
Every signal that clears a detection rule gets checked against a structured set of questions, not just filed away as a vague finding.
- Universal, any category: what’s unmet, where’s the flavor or product gap, where’s the format or packaging gap, which occasions are underserved, where’s the price-tier gap, where are competitors absent from the conversation.
- Rebuilt for chocolate specifically: how health and indulgence framing shows up, how premiumization and gifting behave, what local identity looks like in this market, how climate and convenience shape the category, how channel and experience factor in.
- Discovered from the data itself: specific commercial formats, informal buying and selling behavior, cultural gifting economies, categories consumed as an experience rather than a product, who owns the wellness conversation.
Once something like that shows up with enough evidence behind it, it gets adopted into the framework for every category going forward, not just the one it was found in.
7. Nothing counts as an opportunity until it clears a commercial gate.
Before anything gets presented as a real opportunity, it’s checked against the constraints that actually decide whether a product idea can ship: regulatory and labelling rules, registration, import viability.
An idea that fails any one of those gates is out, no matter how strong the social signal behind it looks. That’s deliberate. We’d rather rule something out early than hand over an opportunity that can’t actually launch.
8. Every signal gets scored, not just flagged.
Clearing a detection rule gets a term onto the board. It doesn’t automatically make it a recommendation. Every candidate gets weighted against seven criteria:
- how big the conversation already is,
- how fast it’s growing,
- how much real white space there is,
- how well it fits the brand,
- how feasible it is to execute,
- what the margin looks like, and
- how durable the trend is likely to be versus a passing fad.
That score sorts everything into one of three tiers: worth prioritizing now, worth exploring further, or worth parking, not chasing, not yet. The output isn’t a report someone reads once. It’s a ranked, living list, an Opportunity Register, that gets rescored on a regular cycle as new evidence comes in.
9. Every trend sits somewhere on one curve, and that decides what happens next.
A score alone doesn’t tell you what stage something’s at. So every term also gets placed on a lifecycle:
- Emerging: a watchlist item, real but too thin to act on yet.
- Rising: where the engagement-outlier and momentum rules actually fire; the only stage worth prioritizing immediately.
- Mainstream: the trend already made it, useful mainly so nobody spends further effort chasing it.
- Past peak/faded: archived rather than deleted, because knowing the exact shape of a trend that already ran its course is how the system recognizes the next real one starting. Instead of mistaking noise for the beginning of something.
This is what that looks like running in practice, not as a diagram:
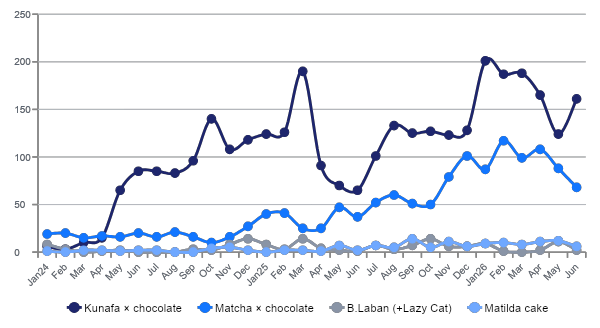
Kunafa has already peaked and settled past its moment, but still a regular part of the category. Matcha is rising fast right now, which makes it the one worth acting on today. B.Laban and Matilda cake are still small, sitting exactly where kunafa was before anyone noticed it. That’s the real value of watching how a finished trend grew: it tells you what to look for before the next one becomes obvious.
The Outcome
The clearest proof of it working: an emerging dessert trend inside the chocolate category was flagged by the engagement-outlier rule roughly six to seven months before it reached its visible peak on social.
One post, using new vocabulary, spiked to well over a thousand times the category’s normal engagement. That single signal fired months before the trend was something anyone outside the category would recognize, let alone act on.
Here’s what that signal turned into over the following two years:
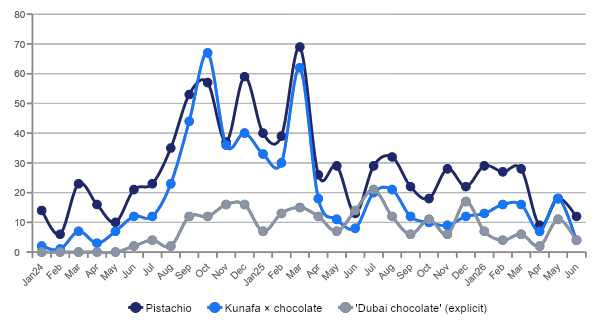
A trend that spikes once and fades was probably a passing fad. Kunafa spiked twice, the second time tied to Ramadan, and never dropped back to where it started. That’s the difference between something people tried once and something that’s now just part of the category.
From there, category findings:
- A specific gifting and occasion format, tied to a major regional holiday (Ramadan), showed real demand and almost no branded presence, even though the same format had already proven itself as a packaged product elsewhere.
- A meaningful chunk of category conversation existed almost entirely in local-language script and phrasing an English-only monitoring approach would never have picked up.
- The brand’s own visibility inside category conversation was significantly behind two competitors. An ingredient-led rival and a gifting-led rival, despite comparable market presence: a gap in cultural conversation, not necessarily in sales.
And because the pipeline itself, not just this one result, was built to be reusable: the same core system, the same screening rules, the same scoring logic, swaps into a new category in under two weeks. Only the category-specific layer changes.
Takeaway
The scrape was never the hard part. Anyone can pull posts off Instagram, TikTok, Reddit, or X.
The hard part was building rules that could tell a real trend apart from noise on their own, without someone eyeballing a spreadsheet and guessing. And then making sure whatever got flagged as an opportunity could actually be launched, not just talked about.
Get that part wrong, and it doesn’t matter how much data you’re sitting on. You’re either watching the wrong things closely, or watching the right thing too late.
Get it right, and the lead time is real: six to seven months in this case. Between the first signal and the moment a trend became obvious to everyone else, including the brand’s own competitors.
Your competitors are already showing up in that conversation. The only question is whether you’re watching it happen, or finding out after it’s over.
Talk to Grepsr about building a social listening system that catches a trend where it actually starts.

Shaping a prosperous future with data-driven decisions
From Product Catalogue to AI Citation: AI Prompt Monitoring for Brand Visibility at Scale
Each passing day, we users skip traditional search engines like Google and Bing for our queries. We directly ask an AI instead, like ChatGPT, Perplexity, or Gemini, and act on whatever answer comes back, often without checking a second source. Even when making a purchase decision, buyers rely on AI. The response is assembled from […]
Beyond the Death: Turning Obituary Data Into Fraud Detection Signals
Every year, pension funds and insurers pay out benefits to people who are no longer alive to receive them. The infrastructure meant to catch a death hasn’t caught up yet, so checks keep getting cut and policies stay active while the record goes unverified. The Social Security Death Master File (DMF) is the default source […]

Competitor Location Monitoring at Scale: Tracking Dealer Network Change Over Time
Markets shift constantly, and most of that shifting happens quietly. A competitor expands into a new region, pulls back from another, and neither move comes with an announcement. For a manufacturer trying to track where rivals are gaining ground, the only real signal is where their dealers show up next. But here’s the thing: a […]

The Hidden Number: How Grepsr Cracked Real-Time Stock Data for a Major Retail Network
Some websites don’t hide their data behind a locked door; they hide it behind a maze. A major retailer’s stock levels were never listed anywhere on its site; the only way to find the real number was to keep adding items to a cart until it broke. This is how Grepsr turned that breaking point […]
The Data Marathon: How Grepsr Keeps Millions of Health Insurance Records and 350+ Data Pipelines Flowing
A partnership story from the health insurance data industry When a New York-based health insurance data and API platform set out to build a standardised data layer for the employee benefits industry, the product vision was straightforward: Give brokers, benefits administrators, and health insurance carriers a single, standardised data layer including provider networks, plan details, […]
Web Scraping for Competitive Market Insights: Powering $3 Billion in EBITDA Through Data-Driven Pricing
Setting prices for products is similar to adjusting the sails on a boat. If you don’t read the wind properly, you’ll either be stuck in place or heading in the wrong direction. Data is the wind that helps you steer a steady course. In an economy where every dollar counts, businesses can’t afford to guess […]
Web Scraping for Drug Safety Monitoring: Real-Time Data Extraction for Tracking Side Effects
Quick Summary: Web scraping and public web data extraction can help pharmaceutical companies detect drug side effects faster by monitoring publicly available discussions and medical publications. This case study explains how a pharma company used web scraping to collect real-time signals about adverse drug reactions and turn scattered public information into structured safety data. Imagine […]
Analyzing Celebrity Impact on Consumer Behavior through Social Media Data: Taylor’s Version
This case study takes a deep dive into the powerful influence of global pop star –Taylor Swift. By extracting social media data using carefully selected keywords and hashtags, we analyze patterns and trends that reflect the powerful gravitational pull of her influence on consumers. Continue reading for jaw-dropping insights. The Power of Celebrity Influence Celebrities […]
Boosting Efficiency and Accuracy: The Power of AI Data Validation for E-commerce Growth
In e-commerce, one wrong product detail can cost you a sale, or worse, a customer’s trust. As businesses scale, ensuring the accuracy and consistency of their data becomes an increasingly complex challenge. Similarly, for a growing electronics retailer, managing an expanding catalog of products with manual data validation was a recipe for errors, delays, and […]
How Proactive Communication Scaled a Product Data Extraction Project for a Dental Supplier
The dental products retail industry is thriving in the online business sector. As more dental professionals turn to digital platforms for sourcing products, those who can harness the power of big data are gaining a competitive edge. One of the most effective ways to leverage this data is through product data extraction—the process of automatically […]

How a Leading Consumer Electronics Company Leveraged Automated Customer Review Extraction
Customer reviews serve as the backbone of product development and consumer insights. For one leading consumer electronics brand, these reviews were essential for fueling machine learning models that perform sentiment analysis and inform key business decisions. However, the frequent removal of reviews by platforms due to policy violations creates significant challenges, leaving gaps in the […]
Powering a Booking Intelligence System with Real-Time Hotel Data Extraction
In the travel industry, booking data is the pulse that reveals how markets move. It captures the patterns of demand, competition, and consumer intent like who’s booking, where, when, and at what price. This information fuels dynamic pricing, helps forecast occupancy, and enables travel platforms and hotels to anticipate market shifts rather than react to […]
How ESG Advisory Firms Can Leverage Automated Article Extraction for Smarter Insights
Government websites and official press releases are goldmines for ESG (Environmental, Social, Governance) intelligence. Every update – whether it’s a new regulation, policy amendment, or court directive can shape how ESG advisory firms advise their clients. Yet, these updates are scattered across hundreds of government portals, each with its own format, language, and publishing schedule. […]
Seamless Vehicle Data Extraction for a Leading Automotive Intelligence Provider
In the automotive industry, having access to comprehensive, real-time vehicle information is essential for making informed decisions. However, gathering this data from online sources comes with many challenges, such as security barriers, IP restrictions, and complex firewall configurations. These can significantly disrupt the flow of critical data needed to support key business operations. In this […]
High-Coverage POI Data Extraction For Powering FMCG Market Strategy
Finding the right retail locations is a lot like navigating a city without street signs – you might eventually reach your destination, but not without wasted time, missed turns, and lost opportunities. Points of Interest (POI) data acts as those street signs, offering clear visibility into where consumers shop, dine, and gather. For global brands […]
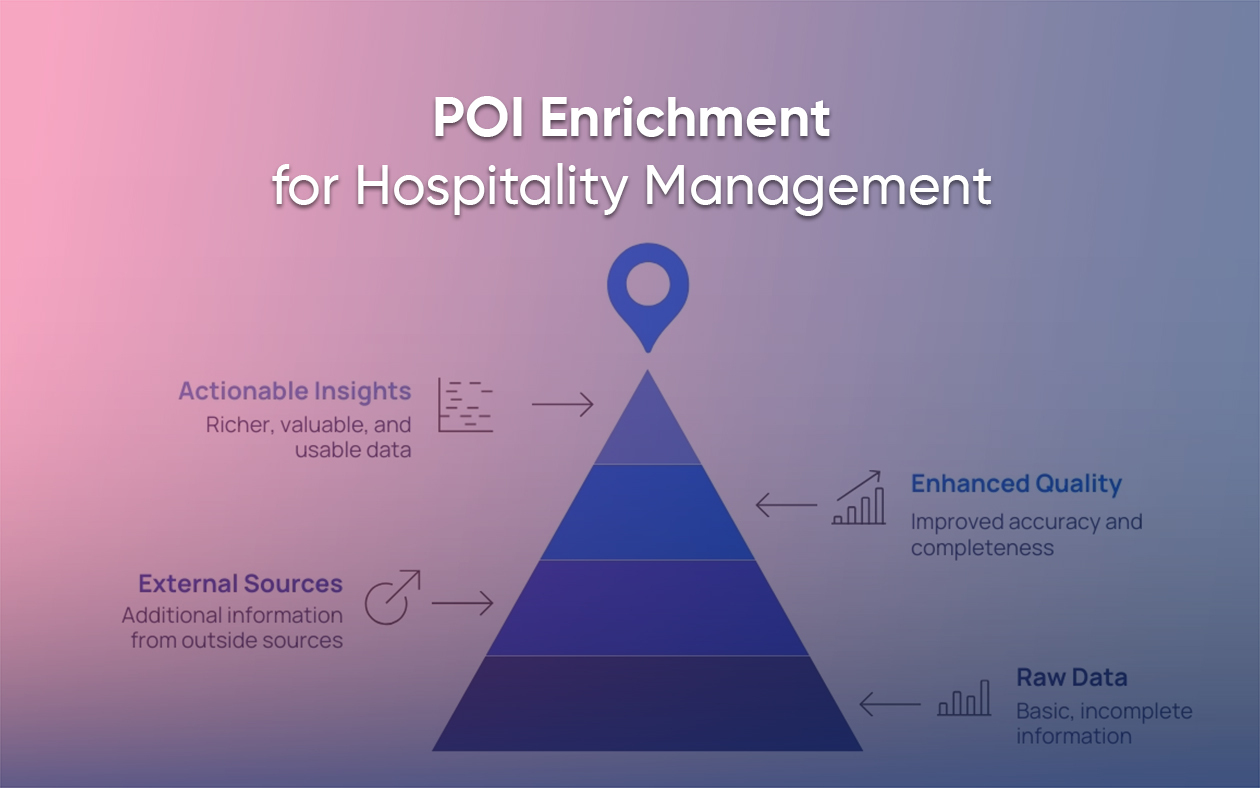
POI Data Enrichment for a Leading Hospitality Management Company
Data is valuable, but enriched data is priceless. Data enrichment is the process of adding value and further information to an existing dataset to improve its quality, accuracy, and completeness. It involves taking raw, incomplete data and enhancing it with additional and meaningful information from external sources. It turns a basic dataset into something richer, […]

Top Six E-commerce Datasets: Web Scraping Use Cases
The irreversible rise of e-commerce has been a similar phenomenon around the world. In 1998, the entirety of the e-commerce market stood at just $5 billion.
Location Intelligence in Retail: Real Use Cases From Grocery Stores
Do you know what separates successful retailers from the ones that are closing down? One key factor is using location intelligence in retail to make informed decisions. Modern retailers scrape the internet to find out competitor store hours, demographic shifts, and foot traffic patterns to find impactful location strategies. And the numbers back it up. […]

Shaping Organizational Culture with Glassdoor Data
Glassdoor Data offers a detailed look into organizational culture by analyzing employee reviews and ratings. This data provides insights into company dynamics, regional trends, and the impact of major events, helping businesses improve employee satisfaction and cultural alignment. Netflix’s culture deck, crafted by Reed Hastings, champions employee autonomy and creativity, even offering unlimited vacations as […]
How Web Scraping Saved a Vehicle Data Platform
How Grepsr rescued a vehicle data platform from a major OEM block—restoring 100% uptime, 99.9% data accuracy, and real-time API performance for VIN checks and insurance quotes.
Mapping LA Wildfire Impact with POI Data
POI data extraction and reverse geocoding transformed wildfire impact maps into precise addresses, enabling targeted disaster relief.
How a Real Estate Agency Gained Competitive Intelligence with Real-Time High-Quality Datasets
Gathering structured real estate data from various government sites and public records at scale poses significant challenges.

What Is Shipping Data & Why It’s Critical for Logistics Performance
Before the pandemic, the global supply chain relied on predictable inventory flows. There was high schedule reliability, which meant the carriers usually followed the same schedules. This ensured the arrival of inventory in time, replenishment of stores, and constant operation of the factories.

Unraveling Job Market Dynamics: Leveraging Data Analytics for Competitive Edge
The notion of hiring the “right” candidate needs clarification of what’s “right” for your organization. Starting from the alignment of values, motivation, ambition, and technical skills required for the position.

Enabling Market Expansion: Data Refinement at Grepsr
Any data is only as good as the insights derived from it. However, before we begin the analysis, the data must be put through adequate pre-processing techniques that standardize, aggregate, and categorize the dataset.

Introduction to Web Scraping & RPA
Web scraping automatically extracts structured data like prices, product details, or social media metrics from websites. Robotic Process Automation (RPA) focuses on automating routine and repetitive tasks like data entry, report generation, or file management.

Car Rental Data Unwrapped: Merry Miles and the Christmas Story in the UK
Delve into the festive drive as we analyze 50K+ car rental records from ‘Sixt – Rent a Car’ during December 2023. From the holiday surges on Christmas Eve to discovering budget-friendly gems like the Kia Picanto, come with us as we decode the Merry Miles of Christmas car rentals in the UK.

NYC POI Data Dynamics: Decoding Impermanence
Geographical locations or POIs are not entities that last for posterity. We collected NYC POI data to decode the various dynamics that may help executives make informed decisions within the backdrop of impermanence.

Revving Up for E-commerce Success in Q4: Leverage Web Scraping
Inflationary pressures, rising prices, and the looming possibility of an impending recession have dealt an unwarranted blow to e-commerce sales over the last three quarters.

Harnessing POI Insights: The Web Scraping Advantage
Points of Interest (POIs) are more than just points on a map. They are filled to the brim with actionable data like addresses, names, contact details, and working hours. POI data also includes images, which add a visual component to the data. With web scraping, you can get the advantage you need to harness POI insights.

Analyzing US Job Postings Data to Understand Job Market & Economy
The US economy was forecast to spiral into a recession in 2023. Yet, despite fears, if current job listings and hiring trends are to be believed, the current economic reality appears to be quite different. The robust nature of the current US job market is proving to be one of the main drivers of the country’s strong economy.
